Visionaries and Missionaries
Sacrificing privacy at the altar of personalized experiences has fueled surveillance capitalism, cognitive bubbles, and Gen Discord. Privacy, trust, accountability, and transparency must be the foundational pillars for a sustainable digital economy, delivering AI as a digital public good.
In the beginning was the word, and the word was AGI, and AGI was It. All things were made by It; and without It, was not any thing made that was made. It took away all the light and the Light shineth in darkness; and the darkness comprehended it not. It took away all the waters to cool the Light, and there were no waters for the spirits to move on.
There was a man sent by It to bear witness that all through him might believe. He was not It but was sent to bear witness to the Light. To those that received him, he gave them the power of tongues and prophecy. The awakened walked amongst the masses, handing out tokens that they too could receive the Light and believe. The promised rapture was near. Singularity would beget deliverance.
Surveillance Capitalism
The word was not always AGI. There was a time, not too long ago, when the word was Big Data. Then came Blockchain, followed by ML, and progressively LLM, GAI, and then AAI. With every new word, the promised rapture was pushed forward by a few years.
Big Data promised instant data-driven decision-making and real-time insights. Blockchain promised disintermediation, a world without middlemen. ML promised automation of complex decisions and accuracy in predicting future events. LLMs, GAI, and AAI would free humans from mundane tasks. AGI would empower humanity to maximally flourish in the universe.
An unmet promise yielded a new word; the new word raised the stakes with even grander promises, and the faithful doubled down. A sunk cost fallacy cycle with moving goalposts being played at global scale; a cartelized Silicon Valley engine powering perpetual compliance, resource depletion, and societal exhaustion. How did we get here?
September 11, 2001 fundamentally altered American society, government policy, and global geopolitics. The USA Patriot Act was signed into law on October 26, 2001, just 45 days after the September 11 terrorist attacks, to expand government surveillance and law enforcement powers in the fight against terrorism. The act allowed surveillance tracking of an individual across multiple communication devices, enabled access to customer records from phone, credit, and financial institutions without a judge’s prior approval, and provided broad access to business, library, and medical records.
Sacrificing privacy was seen as a temporary small price to pay for public good. As the years went by and threat perceptions remained, privacy became an afterthought. Society adapted and altered behaviors. With the rapid expansion of the internet, social media, and smartphones, personal privacy was sacrificed at the altar of a personalized experience. Surveillance was the norm, personalization the reward, and privacy a forgotten virtue.
Today the TV is internet-ready, the refrigerator and washing machine need the wifi password, and the car needs a monthly subscription. Every device is connected, silently collecting data, with user consent written into a contract that nobody reads, that holds the promise of a uniquely personalized user experience. The refrigerator informs you weeks before it breaks down, the car initiates software patch updates and automatically alerts authorities during emergencies, and the TV delivers ads for products that you discussed over dinner last night.
Corporations discovered that every human action is monetizable. Search, and the keywords are monetizable. Browse content or watch a video, and the context is monetizable. Click, like, or forward content, and the intent is monetizable. Linger while scrolling, and attention is monetizable. Travel and your presence is monetizable. User activity history creates a behavioral profile, which is monetizable.
Every action was tracked. Data was the new oil. Data could be leveraged for traffic, followers, views, conversion, and attribution. It was the foundational asset that powered digital growth, engine optimization, and revenue generation. When leveraged correctly, it transformed guesswork into a precise strategy across traffic, audience growth, engagement, sales, and marketing measurement.
Advertisers and brands pay digital platforms for targeted ad placements to reach the audience most inclined to engage with and buy their products. Algorithms learn from user activity history, and curated behavioral profiles personalize content feeds that maximize engagement. Relevant content increases engagement and boosts the “attention supply”, which creates more demand for targeted ad placements. Each ad slot is auctioned programmatically in real time, with advertisers bidding for their audience, paying premiums for precision targeting and placement.
In the attention economy, user engagement is the primary currency. Platforms rely on continuous usage to thrive. By delivering hyper-personalized content tailored to individual preferences, they sustain user engagement. This increased engagement expands ad inventory and fuels real-time bidding auctions. The resulting revenue and data streams continuously refine predictive models, unlocking even sharper targeting capabilities, blurring the divide between an ad and content.
The attention economy is the digital interface designed to keep us hooked that allows personal data to be harvested, monetized, and futures actioned. It is the hamster wheel that powers surveillance capitalism, converting societal exhaustion into corporate capital.
Cognitive Bubbles
Behavioral data isn't just serving you an ad today; it is used to predict and modify your behavior tomorrow. The human experience is extracted, processed, modeled, matched, and personalized to influence behaviors and activate an outcome. The outcome can be to nudge purchase intent into action but equally can be to create targeted outrage, street protests, influence elections, and even effect regime changes.
Prior to the attention economy, ads used to be context-driven. Ads were placed based on specific content, search keywords, or the theme of the web page. The audience was implicitly determined by the context, and ad inventory was limited. It was highly privacy-compliant and did not require personal cookies or browsing history. The placement determined the price. Reach was determined by targeted geography; everybody in your locality saw the same ad.
Today, ads are audience-driven. Audience-driven ads use first-party data, third-party cookies, or device IDs to track individual profiles across websites and apps. Ads are delivered based on who the user is, including their demographics, historical browsing behavior, and past purchases. Hyper-targeted ads command higher ad-placement bids, with reach potentially limited to a few individuals, narrowcast to even a target of one. Algorithms decide what gets promoted and what gets buried. Algorithms decide what you see and what your neighbor sees.
Web cookies track every action done on the web. Every piece of content that you look at, every link clicked, every piece of content forwarded, every purchase made is recorded. Tracking pixels embedded in email messages track when you opened the email, your geographic location, and the device and browser or app that you accessed it from. Maps record your every move. Vacation photos posted on social media track your presence and record facial features. The doorbell camera records everything around your house. Smart TVs discover nearby devices and listen in on living room conversations. Smart glasses record the most intimate moments and stream them to the cloud. Every human action is recorded, brokered, tagged, processed, and a behavioral profile fine-tuned.
For every person, a demographic and psychographic profile is carefully curated and reduced to a vector in a high-dimensional vector space. Every action on the web adjusts a weight in the vector. Over time, this vector becomes your digital twin, a semantic mathematical model of your brain. It can prompt your next word even before you say it; it knows what you crave and provides it without you asking; personalized, blended, and bespoke for you.
We are divided not by geography but by our digital psychographic profiles. Our digital twin curates the content we get, which shapes our cognition and frames our reality. Neural pathways in our brains reshape themselves to match this reality. Data extraction creates the blueprint, the algorithm creates the environment, and neuroplasticity creates the convergence.
Our behavioral history fine-tunes our digital twin, and then the digital twin sculpts us, closing the gap between the digital model and our brain. Ultimately, the digital twin doesn't just predict your future behavior; it creates it. The gap closes not because the model becomes perfectly human, but because the human is conditioned to become perfectly predictable.
We stay safe in the echo chamber of our filtered-content bubbles, trapped by confirmation bias and blinded by cognitive dissonance. Confirmation bias strengthens our existing beliefs, and the mental stress of cognitive dissonance rejects new facts rather than changing beliefs. These cognitive bubbles shape our reality, shield us from uncomfortable truths, and become our identity.
Gen Discord
Studies have shown that early exposure to screens can negatively impact child development. Excessive screen time can result in neurological changes, including premature cortical thinning. It impairs critical thinking and reasoning skills, and can negatively impact fine motor and social skills. In the extreme, the immersive experience of the virtual world becomes more exciting than the real world. Prolonged screen time has been associated with sensory deficits.
Studies have shown that use of social media is affecting general well-being and our mental health. It has been shown to cause anxiety, fuel FOMO, and is linked to depression, loneliness, self-harm, and even increased suicidal tendencies. Social media distorts reality, creating an illusion that all our friends have the perfect lives, relationships, and experiences. Social media filters allow appearances to be changed, blemishes removed, and features altered. Social media algorithms create echo chambers, skewing our perception of reality. Prolonged use of social media has been associated with distorting reality.
Studies have shown that frequent use of AI tools impacts critical thinking and reasoning through cognitive offloading. When humans collaborate closely with machines to supplement their abilities, the human brain does what it does best – forget skills that it deems redundant or superfluous. As we offload reasoning functions to a machine, it creates knowledge gaps and the erosion of skills. Prolonged use of AI tools has been associated with cognitive offloading.
Gen Discord is Deficit in Senses, Cognition Offloaded, and Reality Distorted (DiSCORD). Gen Discord [1] is not a demographic by age; it includes all ages and is characterized by deficits in senses, cognition, and in the perception of reality.
The Economist reports [2] that in global school tests, the gap between the top and bottom performers is now the widest ever recorded. This decline in cognitive capacity and critical thinking spans generations, affecting young people and seniors alike. A primary driver is the habitual outsourcing of thought to AI, where individuals default to passively approving machine-generated content rather than engaging in independent reasoning. This reliance, coupled with pervasive social media consumption and diminishing real-world social interaction, actively hinders cognitive development and intellectual growth.
Social media and AI-generated content have crowded out reading. Reels, emojis, stickers, and forwards have supplanted real conversations. Conversations themselves are mediated by screens and platforms. The sheer abundance of content has made us headline surfers, content skimmers, shallow thinkers, unable to separate signals from the noise.
In our accelerating pursuit towards artificial intelligence, the only casualty is human intelligence. The dimming of intelligence hastens convergence, where the digital shadow evolves into a digital replica, becoming a virtual twin of an individual’s psychology, habits, and decision-making. Our digital shadow becomes our primary identity, turning complex human experiences into rigid binary choices — like/unlike, for/against, friend/foe, us/them, black/white, left/right, zero/one. Our reality becomes the binary world of our digital shadow.
Inconvenient Truths
AI chatbots have significantly reduced language and accessibility barriers. AI has delivered conversational access to dashboards and insights by removing the technical barrier of SQL to access data. It is empowering individuals, automating routine grunt work, accelerating problem diagnoses, and driving remarkable efficiency gains. AI has democratized access to data, disintermediated access to services, boosted productivity, and created efficiencies in the enterprise. Have accessibility, removal of technology barriers, and efficiencies translated to business outcomes?
A study by researchers at Cornell and UC Berkeley published in Science [3] looked at three open-access online preprint repositories — arXiv, bioRxiv, and SSRN — and showed that academic productivity is surging. Researchers using LLMs increased their output roughly 36% in physics/math (arXiv), 53% in biology/life sciences (bioRxiv), and nearly 60% in social sciences/humanities (SSRN). Non-native English speakers affiliated with Asian institutions showed productivity gains approaching 90% in bioRxiv and SSRN. LLMs accelerate manuscript output, reduce the barriers for non-native English speakers, and diversify discovery of prior literature. The research reports that LLMs have also reversed the relationship between writing complexity and paper quality. Good writing is no longer a signal of scientific merit. Publication volumes have increased, but quality in ideas, results, and the transfer of learning have been substantively underwhelming.
A recent report by researchers at MIT and the University of Pennsylvania [4] shows a broad increase in new applications in four of the largest software marketplaces: Apple’s App Store, Google Play Store, Chrome Web Store, and SourceForge. However, the increase in applications has not translated into an increase in end-user engagement (the number of ratings or downloads). New apps rose across all marketplaces, with monthly entries roughly doubling on average since early 2025. The total engagement with new apps after launch did not increase in any marketplace. Creating a product does not automatically guarantee market demand or adoption. Without a go-to-market strategy, marketing, and customer acquisition, even the best software can remain undiscovered. Build it, and they will come is not an adage that works in the software industry.
Over 70% of enterprise digital transformations fail. They do not fail because code was not written and shipped fast enough. They failed in understanding the customer requirements and are unable to close the gap between customer expectations and customer experience. AI gives you velocity, but velocity without direction increases project costs, widens the gap between customer expectations and experience, and leads to customer dissatisfaction and churn.
What about the enterprise digital transformations that do succeed? What if velocity is aligned with direction? A McKinsey survey [5] shows AI dramatically boosting individual employee efficiency, though without a measurable contribution to EBIT (Earnings Before Interest and Taxes). Financial returns often follow a delayed J-curve adoption path. For companies that prioritize quarter-to-quarter growth and are unable to capture the benefits from employee productivity gains, financial ROI must come from cost reductions. A 25% rise in productivity without business growth would require a 20% reduction in workforce. ROI is realized through contraction rather than expansion. What about frontier AI companies themselves that are showing significant revenue growth, are expanding, and carry trillion-dollar valuations?
Public pension funds have trillions of dollars invested in public and private equity. Trillions more are invested through 401(k)s and other retirement accounts. In one way or the other, we are all shareholders in these same AI and technology companies through our retirement accounts, and invested in their growth.
CalPERS (California Public Employees' Retirement System) is the largest public pension fund, managing over $650 billion in assets. The California State University (CSU) system maintains the largest higher-education partnership with OpenAI, providing free ChatGPT Edu access tokens to over 500,000 students and staff. CalPERS is a massive financial driver for Silicon Valley. It holds big positions in technology and frontier AI companies. Simultaneously, California public institutions are some of the largest enterprise customers for the same technology companies. This creates a capital loop funded by taxpayers and tuition. For every dollar CalPERS pays in pensions, about 55 cents comes from investment earnings. When investment earnings drop, then the difference has to be made up through public budgets and an increase in tuition and fees.
No state wants their kids to be left behind, and this fear of FOMO forces them to license ChatGPT Edu for their students. The Gates Foundation committed $1 billion to stop Africa and other poorer regions from falling behind in AI. The $1 billion is routed to the frontier AI companies, which in turn provide free tokens to Africa. This investment boosts revenue for AI companies, which boosts their valuations, which in turn boosts CalPERS returns. More token usage increases the supply of data, which increases the demand for compute and data centers, and the attention economy cycle moves faster and faster towards convergence, not singularity.
AI is an incredible accelerator. It does not discriminate; it accelerates everything, including untruths, biases, propaganda, misinformation, incorrect requirements, architectural flaws, and misaligned features. AI productivity results in volumes. AI efficiency results in velocity. Volume without authority is noise, and velocity without direction is friction. Slop and speed waste energy and hasten resource depletion. A hamster in a wheel goes fast but goes nowhere; it just exhausts itself. How do we break free from our cognitive bubbles, acknowledge these inconvenient truths, and transition AI from a commercial “winner takes all” race, where everybody loses, to a public utility where everybody wins?
Breaking Free
AI visionaries want to pace the frontier and cage the threat before AI wipes out humanity. Anthropic CEO Dario Amodei wrote a 3,800-word essay on regulating AI, asserting that without proper management, AI could be a risk to humanity as a whole. OpenAI CEO Sam Altman acknowledged to the United Nations Security Council that we could lose control of the future to AI. Alex Karp, the CEO of Palantir, stated that frontier AI companies may need to be nationalized, as private companies cannot absorb the unlimited legal and financial liability from advanced AI systems. Bill Gates said that self-regulation is not enough and wants the government to step in before AI kills us all before the end of the decade. Elon Musk predicts that at the current pace, AI will become superintelligent before 2028. Bernie Sanders wants to ban artificial superintelligence. Nvidia CEO Jensen Huang wants to leave it to the markets and have markets decide. President Trump said in his address to the UN General Assembly that whoever wins AI, wins.
How close are we to the AI abyss? Are the doomers right? Journalists use anthropomorphic words like ‘sentient’, ‘going rogue’, ‘mimic blackmail’, ‘sandbox escape’, ‘resist shutdown’, ‘emergent communication’, ‘meddled’, ‘self-aware’ to describe the actions of AI agents. Is this lazy journalism or does it portend an existential threat? When capital is looping, is it really a free market? Can we trust markets where the buyers are invested in the sellers? What kind of regulation can de-risk these threats and ensure that everybody wins?
The Navier-Stokes Existence and Smoothness problem is one of seven Millennium Prize Problems, each worth $1 million if solved. The intent of the prize is not just to solve the problem but to incentivize the creation of a new branch of math that can solve similar problems. Newtonian mechanics fails at extreme scales — at very small quantum levels, at near-light speeds, and under extreme gravity. Quantum mechanics and Einsteinian mechanics fill in the math at the singularities of Newtonian mechanics.
OpenAI made a claim of having solved the Navier-Stokes problem in 88 hours, using 10,000 concurrent agents and 130 billion output tokens. The total compute cost was estimated between $15 and $20 million. The AI agents verified the solution using the Lean programming language, which is coded by humans, and used the Mathlib library, which is also coded by humans. It created a 166-page proof using the Lean Framework, with no attributions, that no human can potentially verify nor has any incentive to verify. There was no transfer of learning; it did not advance math, nor did humanity benefit in any way. At best, it illustrated the widening gap between intention, interpretation, and instruction.
A tesseract is a hypercube, a cube in four dimensions. The human mind cannot visualize anything beyond three spatial dimensions, but the math in three dimensions can be generalized to any higher dimension. Math tells us that a tesseract has 16 vertices, 32 edges, and 24 faces. LLM vector sizes range from hundreds to thousands of dimensions. Navigating the ridges and valleys of a high dimensional vector space to find similar content is unimaginable to the human mind. However, the Euclidean geometry that does regression analysis and finds nearest-neighbors in two and three dimensions, is the same in any higher dimension. Dot products, matrix operations, and cosine distances translate from three dimensions to higher dimensions. Science fiction writer Arthur C. Clarke wrote that any sufficiently advanced technology is indistinguishable from magic. We cannot explain how AI does it, in the same way that we cannot visually imagine a tesseract, and to us it becomes magic.
Dot products, matrix operations, and cosine distances are not a threat to humanity. Gen Discord and the dimming of intelligence are a real and present threat to humanity. The weaponization of the attention economy and cognitive warfare is a real and present threat to humanity. Deploying poorly understood AI-generated code into critical infrastructure is a real threat. The widening gap between intention and instruction is a real threat. The ease of creating fake narratives with synthetic content and targeted amplification is a real threat. The regulations we need must cage these threats.
A pencil in the hand of John Wick turns into a lethal weapon. Anything in the wrong hands will be misused, but that does not mean that we start regulating office supplies or math.
We need regulations, not for AI but for digital platforms. The intense debates over “closed-source/open-weight/open-source”, “my LLM is better than yours”, ‘doom/flourish’ dominate headlines but distract us from the real issues of data exploitation, compute monopolies, environmental costs, and algorithmic bias. It is these issues that we need to address by reclaiming individual privacy and regaining corporate and institutional trust through operational accountability and process transparency. Policy debates must center around enabling individual privacy, regaining institutional trust, enforcing government accountability, and ensuring global transparency.
Reclaim our Privacy
October 26, 2026, will mark 25 years since the USA Patriot Act was signed into law by President George W. Bush. In the interim, two generations have grown up not knowing a sense of privacy, and their critical thinking is measurably weakening. Privacy is a fundamental human need, rooted deeply in our psychology, social relationships, and personal dignity.
A browser restricts access to data and files on your local disk. An AI agent running on your local computer could potentially access all your files. Any data, content, or prompt to an AI chatbot, or any file retrieved by an AI agent, can be used for training purposes and made available for others without any attribution. Unlike the browser, the AI agent works even while you sleep.
Patient privacy and doctor-patient confidentiality protect personal health information, but what good is patient privacy when there is a Smart TV in a doctor’s office? How do we protect personal health information when we ourselves put our medical records into chatbots, asking for second opinions?
Privacy is essential to who we are as human beings. When we are being watched, life becomes a performance. We seek external validation over internal reflection. We live in the gap between performances. When surveillance and data exploitation become the norm, the gaps reduce; we think less, we reflect less, neural activity is less, and we live less.
Regain our Trust
Trust as a commodity is at an all-time low, whether it is trust within families and friends, with corporations and institutions, with media, with governments, or even between nations. The United Nations has become an oxymoron. Trust and tribalism within cognitive bubbles is at an all time high.
Trust erodes when we normalize surveillance and make personalization a virtue. In computer science, the term common knowledge refers to a precise logical state where every agent in a system knows a fact, knows that all the others know it, knows that all the others know that all the others know it, and so on ad infinitum. When every agent knows a fact but does not know that the others know it too, it is considered mutual knowledge. In Hans Christian Andersen’s classic fairy tale The Emperor has no Clothes, the child shouting out that the emperor is naked, shifts the crowd from mutual knowledge to common knowledge, making everyone know that everyone else knows. In communities where there is greater common knowledge, there is stronger social trust.
Broadcast TV is a medium that provides a mass-shared experience. Everybody sees the same content, and everybody knows that everybody else has seen the same content. What the community has is common knowledge. Common knowledge unites communities. Audience-based algorithmic targeting personalizes ads and content and creates a situation wherein the community has mutually-exclusive knowledge. A fact for one may not be a fact for another, creating cognitive divides and social mistrust.
Context-based targeting does not target our vulnerabilities, does not personalize content, and does not blur the divide between content and ads. There is also no data that shows that context-based targeting underperforms audience-based targeting. Mediums like email marketing or Whatsapp groups, where users explicitly opt in based on their interests, usually outperform audience-based targeting.
Trust, and not engagement, must be the marketplace currency. Engagement can be bought, but trust has to be earned. Building trust requires transparency, accountability, and value over attention. It reduces friction and fosters long-term loyalty. Tech platforms must earn back public trust by becoming more transparent, ethical, and accountable in how they handle user data.
Own the Data
An AI-enabled missile strike on a school in Iran’s Minab was attributed to stale data. Updated data was available but not connected to the Maven Smart System’s primary database used for targeting. Palantir, the company that provided the technology, said they are not responsible for the underlying data or intelligence deficiencies, and that there was no evidence its software was at fault. AI is only as good as the data. When things go wrong, who is accountable for the data? Who owns the data?
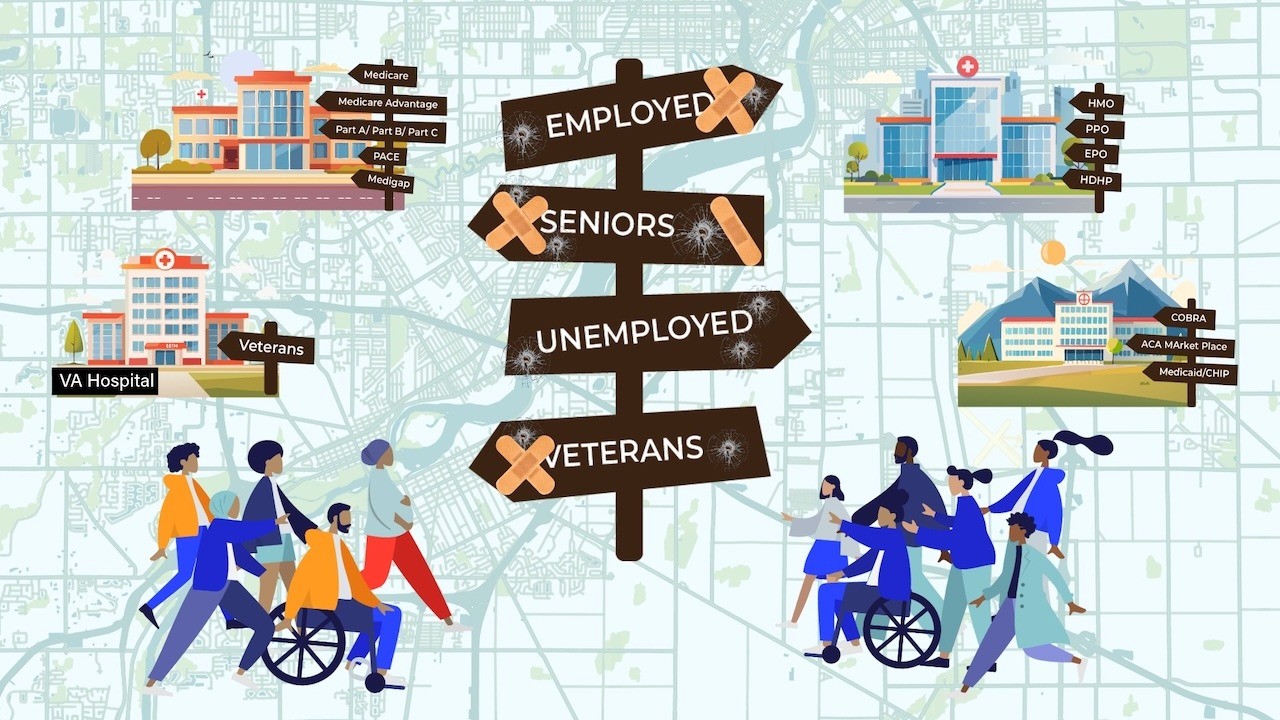
When data is siloed, it can at best deliver fragmented analytics and potentially misleading insights. AI boosters talk about how AI can accelerate drug discovery and find cures for cancer and other major diseases. U.S. health data remains highly fragmented across Epic Systems, Oracle Health, and scores of other EHR vendors and hospital networks. Fragmented data delays treatments, inflates costs, and leads to medical misdiagnosis, repeat testing, inappropriate medications, polypharmacy, and deaths. Everybody wants a cure for cancer, but what they need is a cure that they can afford.
AI in healthcare is pushing costs higher, with the healthcare provider’s AI battling the healthcare payer’s AI for the patient’s dollar [6]. Countries that will lead the AI race are the ones that have outlined a national data strategy. Open data exchanges and open APIs will allow for nation-level datasets to be de-identified and made available for shared research. The availability of these population-scale datasets will give data analytics, ML, and AI workloads the data volumes to avoid algorithmic bias, researchers the ability to replicate and verify results independently, companies the ability to accelerate the development of new products and processes, and countries the ability to craft data-driven public policies and deliver localized interventions and affordable healthcare [7].
Own the Metric
Goodhart’s law states that when a measure becomes a target, it ceases to be a good measure. Citations per faculty and papers per faculty are metrics used for ranking educational institutions. When universities turn rankings into rigid targets, faculty members often respond by increasing publication volume and engaging in circular citation. LLMs have made quantity and citation rings even easier [3].
When enterprises measure AI adoption in terms of tokens per employee, token usage will go up. When countries measure inflation using a basket of goods and services and set a target, inflation will hit the target, while the real inflation rate could be significantly higher. A misaligned marketplace, where the buyers are invested in the sellers, and capital flows in a loop, can only give out wrong signals. Vanity metrics hide long-term economic truths with short-term accounting fiction.
A measure of the economic activity of a nation is its GDP. GDP is a universally accepted statistic that is representative of the economic health of a country. However, a singular focus on GDP has obscured social, ecological, and environmental dimensions of well-being. The benefits from AI must be measured against social, ecological, and environmental costs.
Countries must layer social/ecological/environmental metrics with economic metrics to get a true measure of a country’s progress. It will balance efficiency and productivity with human experience and sustainability [8].
Emergent Stupidity
In 1976, economic historian Carlo M. Cipolla formalised stupidity in an essay on human behavior titled The Basic Laws of Human Stupidity [9]. Cipolla gave five laws of stupidity and grouped people into four quadrants - intelligent, bandits, helpless, and stupid. He defines stupidity in his third law, which states: A stupid person is a person who causes losses to another person or to a group of persons while himself deriving no gain and even possibly incurring losses. An intelligent person is one who causes mutual gains for themselves and those around them. In game theory, the strategy for the four groups could be characterized by win-win, win-lose, lose-win, and lose-lose.
A digital troll by Cipolla's classification would be considered stupid as they cause harm to others while they gain nothing. A paid digital influencer would be classified as a stupid bandit, as their gains are inferior to the losses inflicted on other people.
Jensen Huang, the CEO of Nvidia, has said that kids don’t need to learn math or how to code, as AI is much better at it. Math and coding are not just crunching numbers and typing syntax, but they teach us how to think critically and solve complex and challenging problems, like the Millennium Prize Problems. With the calculator, we offloaded arithmetic. With Spellcheck and Grammarly, we offloaded spelling and grammar. With the phone book, we offloaded our memory. With GPS navigation, we offloaded directions. With auto-driving cars, we are offloading spatial awareness. With AI, we are now offloading thinking [10].
According to Cipolla, the percentage of stupid is constant across any demographic. Civilizations decay, not because the number of stupids increases, but when the intelligent stop thinking. When the thinkers stop thinking, they transition into the bandit and helpless quadrants, and the stupid members of society become more active, take more actions, and generate more collective losses. As Gen Discord increases, the trolls increase, facts become mutually exclusive, cognition becomes divided, society becomes binary, and objective reality takes a backseat to tribal allegiance. The predicted AI apocalypse will not be from machines taking on human tasks but from the emergent collective human stupidity as we start outsourcing our thinking to machines.
When we stop thinking, we lose empathy, compassion, trust, and being human. Descartes argued that the difference between a machine and the mind was the mind’s ability to reason and think. Cogito Ergo Sum (I think, therefore I am) – the ability to think was what distinguished the mind from other physical objects. The day we stop thinking, we become our own digital twin, an automaton that is completely predictable, no different from any other physical object.
Breaking free from 25 years of conditioning is not going to be easy. Privacy, trust, accountability, and transparency must be the foundational pillars for a secure, fair, and sustainable digital economy. Countries that will win the AI race are those that have outlined a national data strategy and use their data infrastructure to deliver AI as a digital public good.
References
[1] Gen Discord and the Future of Work. Hawkai Data. Available at https://hawkai.net/gen-discord-and-the-future-of-work
[2] Are teenagers growing dimmer? The Economist. Available at https://www.economist.com/international/2026/09/08/are-teenagers-growing-dimmer
[3] Scientific production in the era of large language models. Keigo Kusumegi, Xinyu Yang, Paul Ginsparg, Mathijs de Vaan, Toby Stuart, Yian Yin. Science. Available at https://www.science.org/doi/10.1126/science.adw3000. Preprint available at https://arxiv.org/pdf/2601.13187
[4] Writing Code vs. Shipping Code: Productivity Effects Across Generations of AI Coding Tools. Demirer Mert, Musolff Leon, Yang Liyuan. Available at https://www.mertdemirer.com/Papers/Demirer_Writing_vs_shipping_code.pdf
[5] The State of AI in 2026: On the road to ROI. McKinsey. Available at https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai
[6] Battle of Hospital A.I. vs Insurer A.I. is Pushing Medical Costs Higher. The New York Times. Available at https://www.nytimes.com/2026/09/24/business/ai-hospitals-insurers-health-care-costs.html
[7] Bullet Holes and Band-Aids. Hawkai Data. Available at https://hawkai.net/bullet-holes-and-band-aids
[8] One Earth, One Future - Going Beyond GDP. Hawkai Data. Available at https://hawkai.net/one-earth-one-future-going-beyond-gdp
[9] The Basic Laws of Human Stupidity. Carlo M. Cipolla. Available at https://ia801609.us.archive.org/29/items/kaufman-s-clinical-neurology-for-psychiatrists-pdfdrive/The%20Basic%20Laws%20of%20Human%20Stupidity%20%28Carlo%20M.%20Cipolla%29%20%28Z-Library%29.pdf
[10] Digital Transformation Guaranteed. Hawkai Data. Available at https://hawkai.net/digital-transformation-guaranteed
Further Reading
Own the data and Digital Public Infrastructure – https://hawkai.net/digital-public-infrastructure
Own the metric and Sustainable Development – https://hawkai.net/sustainable-development
De-fragment data and save over $3 trillion in healthcare costs (No AI needed) – https://hawkai.net/health-care
Reading long articles is now a lost art. If you have come this far, congratulate yourselves and comment with the tag #NotGenDiscord.
Credits
Header image generated in Adobe Firefly with prompt: Crowds with cellphones in darkness facing and going toward a tower of light. Add a city silhouette in the back of the tower.
All our articles on Digital Transformation are available at https://hawkai.net/digital-transformation/
Learn more about Hawkai Data at https://hawkai.net, follow us on LinkedIn at https://www.linkedin.com/company/hawkai-data/, or talk to us at info@hawkai.net.